Mingyang Liu
I am a quantitative researcher, currently a Visiting Researcher at the Imperial Centre of Excellence in Quantitative Finance, Imperial College London, hosted by Prof. Robert Kosowski. My primary research fields are empirical asset pricing, machine learning and big data in finance, and financial econometrics. Working with large panels of stock characteristics and regularised machine-learning estimators, I ask which parts of a factor model’s answer (its factors, its alphas, its portfolios) reflect information in the data, and which reflect only how the model measures that information. I follow these measurement choices from identification and inference to the portfolios an investor ends up holding.
Separately from my papers, I build and test analysis tools for investment research: the Research Toolkit shows each one run on an archived research example, with its inputs, outputs and limits stated.
I received my PhD in Finance from Imperial College London in 2026, supervised by Prof. Paolo Zaffaroni and Prof. Pasquale Della Corte, after an MRes in Finance with Distinction (2020). Before Imperial, I earned a B.S. with a double major in Economics and Mathematics (Mathematics of Finance and Risk Management track) from the University of Michigan and an M.A. in Economics (Financial Econometrics) from Columbia University, where my master’s thesis was supervised by Prof. Jushan Bai.
Alongside my research, I work as an independent quantitative research and AI/ML consultant. I have advised emerging systematic investment teams in China on research data and feature engineering, Python research platforms and the use of AI coding agents (see Independent advisory).
Name variants: Mingyang Liu · Liu Mingyang · Yang Liu (legal name, used in some listings) · 刘明杨 · 刘杨.
| Characteristic | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 |
|---|
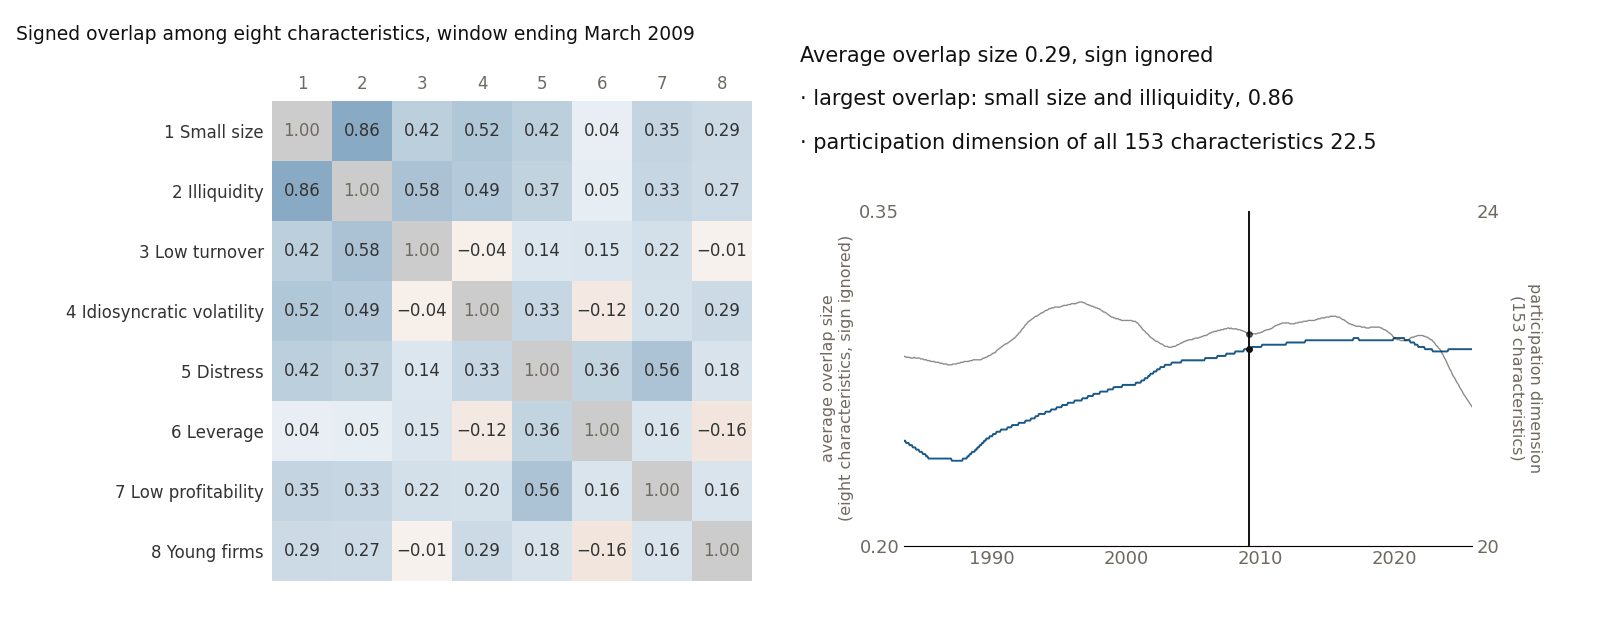
Scale of the signed overlap: +1 means the same stocks score high on both, −1 the opposite. A value of 0 means the scores do not line up. Each characteristic is signed so that the named trait scores high. Diagonal cells are 1 by construction. The average in the readout ignores the sign.
Use the slider or the arrow keys to move the window; the table updates.
Across the windows the average size of the overlaps ranges from 0.24 to 0.29. The overlap between small size and illiquidity ranges from 0.61 to 0.93. The participation dimension of the whole library stays between 21.7 and 22.9.
Figure 1 shows what the characteristic ruler measures and the plain ruler assumes away: how much eight related characteristics overlap across stocks, re-estimated each month from 1983 to 2025.1 The next section explains what a ruler is, and why switching rulers changes how returns are split between factors and the part no factor explains, and what an investor holds.
Research agenda
Same information, different answer: before trusting what a factor model says, check its ruler.
A factor model explains many stocks’ returns with a few common drivers. Built on stock characteristics (size, value, momentum and many more), it gives three answers: which risks are priced, how much expected return its factors leave unexplained (the alpha), and what to hold. I ask how much of each answer comes from information in the data, and how much from choices that add no information. The central choice is the ruler. To credit a stock’s expected return to its drivers, a model must first decide when two combinations of characteristics are really different and how large each one is. The rule it uses for that is the ruler: technically, a metric (an inner product) on characteristic space. I estimate the ruler from the data. I show that changing it changes how returns are split between the factors and the part no factor explains (the intercept; the alpha is a close relative, measured against a stated benchmark model), but not how well they are fitted, and I carry the ruler’s own estimation error into the confidence intervals. I then ask what a smaller alpha really reflects, and how the ruler, and the library of characteristics it measures, change what an investor holds. Researchers and portfolio managers change such conventions routinely, and a change of convention is easy to mistake for a discovery.
Give each characteristic a weight and add them up: every stock gets a score. Such a weighted combination is called a direction (it is not a portfolio). The plain ruler (the Euclidean or identity metric) judges a direction by its weights alone. The characteristic ruler (the Gram metric) judges it by the scores it gives real stocks: how large they typically are, and whether two directions’ scores line up across stocks, high on the same stocks and low on the same stocks.
The ruler is the convention a model uses to measure how large a direction is and how much two directions overlap. Two value signals that pick out the same cheap stocks count as overlapping under the characteristic ruler but as unrelated under the plain ruler.
Read in this order
Each paper holds everything else fixed, changes one choice, and asks what moves.
- Which ruler? → Geometric Framework (earlier, broader version)
- What does the ruler decide, and how reliable is the answer? → Characteristic-Space Metrics
- What does a smaller alpha mean? → Interpreting Pricing Errors
- Same forecast, different portfolio? → Same Forecasts, Different Portfolios
- Same target, different stocks? → The Ruler Matters
Research
A Geometric Framework for Identification in Characteristic-Based Factor Models
Same data, different factors: which combinations of characteristics count as distinct depends on the ruler. The paper takes the ruler (the Gram metric) from how characteristics spread and overlap across stocks, and builds identification, no-arbitrage restrictions and inference on it.
Earlier, broader version of Characteristic-Space Metrics.
Paper page · PDF · SSRN
Characteristic-Space Metrics in Factor Models: Identification and Inference
Same fitted returns, different split: the ruler decides how returns are credited to latent factors (common drivers inferred from the data), observed factors such as the market, and an intercept. When the ruler is estimated from the data, its error belongs in the confidence intervals.
Paper page · PDF · SSRN
Interpreting Estimated Pricing Errors: Evidence from Characteristic-Based Return Forecasts
Same ruler, different target: an alpha can shrink because the factors explain more, or because the expected-return estimate they must explain (the target) has changed. Pairing each model’s estimate with each model’s factors on the same stocks, the paper finds that the large alpha gap between equal-weighted and value-weighted training mainly reflects different targets.
Same Forecasts, Different Portfolios: Factor Normalization and Regularization
Same forecasts, different portfolios: the small constant a portfolio rule adds to each factor’s risk is a penalty on factor bets, written in the ruler’s units, so one number gives two portfolios. With the same number, two versions of one model that forecast alike have Sharpe ratios (average excess return per unit of volatility) of 0.69 and 1.07 before trading costs (Table I, p. 19). Written in one set of units, or removed, the penalty gives one portfolio.
The Ruler Matters: Factor Exposures, Attribution, and Portfolio Risk
Same target, different stocks: a factor model that fits returns better need not represent the positions an investor cares about, and whether a hedge removes the model’s factor loadings depends on the ruler that measures them. Expanding the library from 36 to 153 characteristics raises in-sample fit, yet the model’s loadings then represent momentum and size positions less fully; hedging a value position with the plain ruler leaves, on average, 46.10% of the hedged position, by squared stock weight, still on the model’s factor loadings (pp. 6–7).
Paper page · Paper (PDF) · Slides, one-hour talk (PDF) · Video explainer (6 min)
Research in progress. Exposure or Intercept? Identifying Corporate Bond Premia with No-Arbitrage IPCA, with Paolo Zaffaroni (in preparation). An ongoing research collaboration with Prof. Semyon Malamud (EPFL and Swiss Finance Institute) on portfolio construction from linear out-of-sample return forecasts. See Research in progress.
Path
Ann Arbor · 2014–2017
University of Michigan
B.S., double major in Economics and Mathematics
Photo: University of Michigan
New York · 2017–2019
Columbia University
M.A. in Economics (Financial Econometrics)
London · 2019–2026
Imperial College London
MRes in Finance (2020) and PhD in Finance (2026); Visiting Researcher from 2026
Photo: Imperial College London
Contact
| mingyangliu.org@outlook.com · yang.liu19@imperial.ac.uk (academic) | |
| Imperial profile | profiles.imperial.ac.uk/yang.liu19 |
| linkedin.com/in/mingyang-buweinan | |
| ORCID | 0009-0008-5418-2563 |
Characteristics: the Jensen–Kelly–Pedersen library of 153 U.S. stock characteristics (JKP153), the same library that The Ruler Matters uses, each characteristic rank-centred within the month and signed so that the trait named in the row scores high. Each window averages, with equal weights, the monthly 153×153 second-moment matrices of these characteristics over the 240 months ending in the month shown. Window ends run from June 1983 to November 2025. There are 510 windows, and no future months enter any window. The 240-month equal-weighted window is this exhibit’s own choice. Same Forecasts, Different Portfolios reports the rolling-60, equal-120 and EWMA (exponentially weighted moving average) versions of the characteristic ruler (p. 17), and the path depends on the window. The table takes the 8×8 block for market equity (sign reversed), Amihud illiquidity, turnover (reversed), idiosyncratic volatility, a distress score (Ohlson O-score), debt to market equity, operating profitability (reversed) and firm age (reversed), and rescales it to unit diagonals, so the cells are approximately correlations. The block is a chosen high-overlap corner of the library, not a representative sample; summaries of the overlaps among all 153 characteristics are in Characteristic-Space Metrics, Table I (p. 31) and Figure 1 (p. 32). The most overlapping pair is small size and illiquidity in every window; Amihud illiquidity is built from dollar volume, so a large overlap with size is expected. Accounting inputs change only when new financial statements are filed, and coverage, the share of missing values and the stock universe change over time; those changes move these averages as well as any change in how firms line up. The participation dimension in the timeline is computed from the full 153×153 window matrix, not from the 8×8 block, and runs from 21.7 to 22.9. This is a descriptive visualisation, not a new estimator or causal test.↩︎